Exclusive 40% Discount: Deterministic AI on CPUs – Build Low-Latency LLM Workflows
Special 40% Discount for the IBridgePy Community
Save 40% using promo code HUI40 or register directly through our partner link below.
Generative agent tutorials break down where production engineering starts: context drift, JSON schema parsing failures, compounding API latency, and crippling cloud costs.
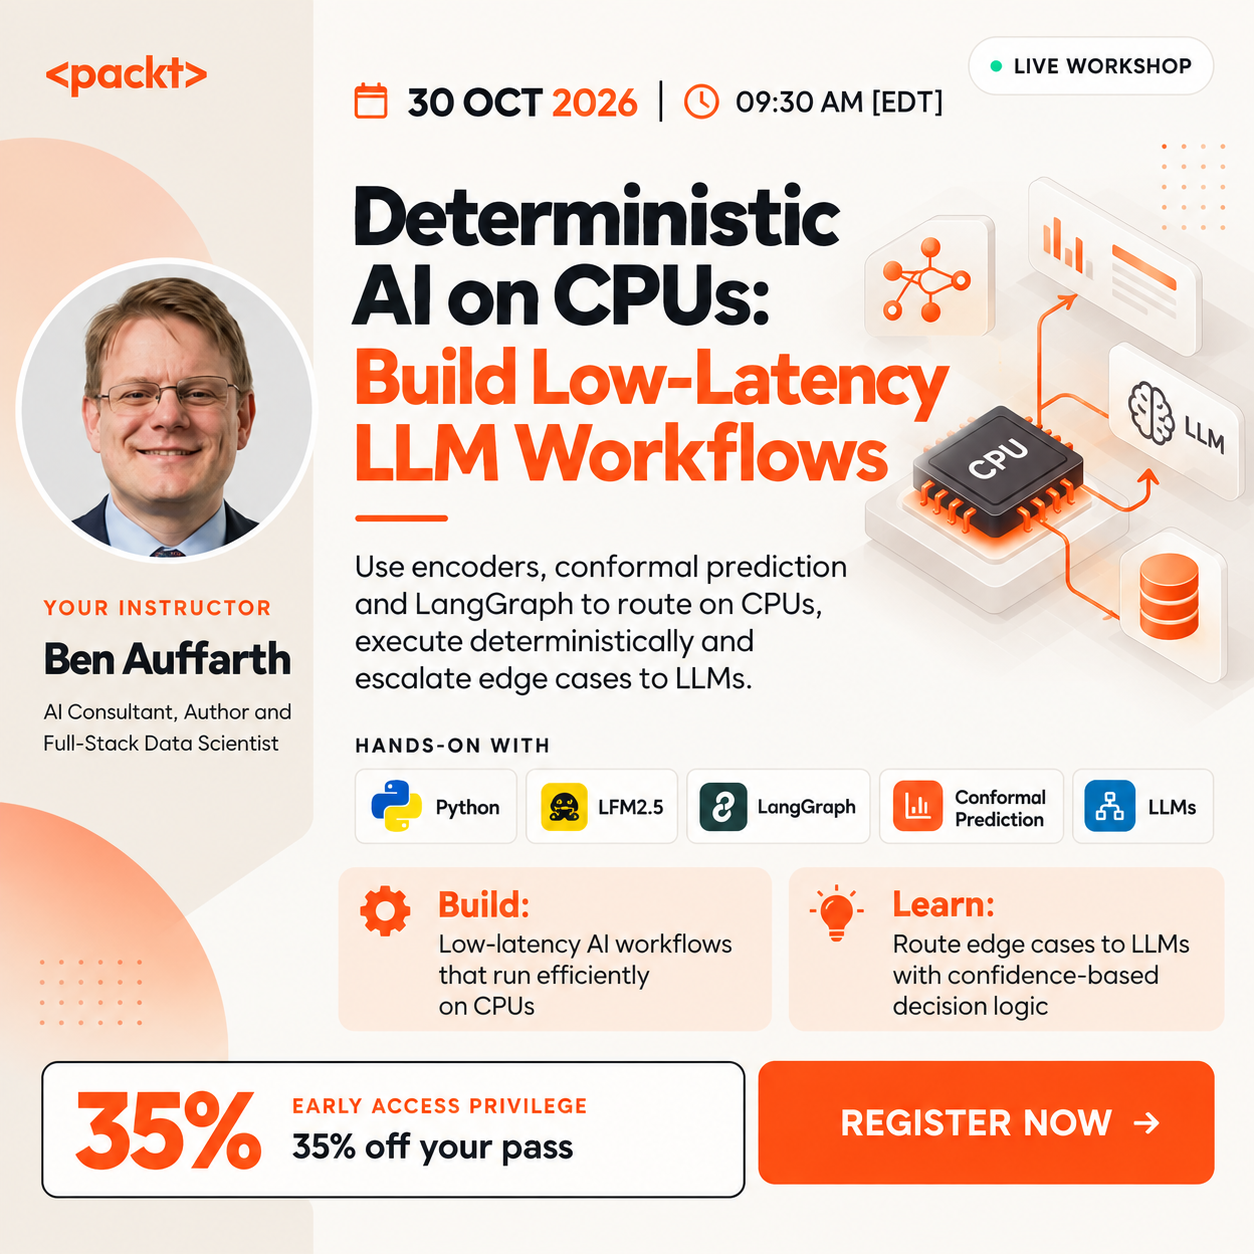
In this live build lab, AI architect and bestselling author Ben Auffarth, PhD demonstrates how to build deterministic, ultra-low-latency AI architectures that run locally on standard CPUs. You will replace fragile prompt loops with bidirectional encoders (LFM2.5 and ModernBERT), calibrate uncertainty bounds with conformal prediction, orchestrate idempotent execution in LangGraph, and restrict expensive LLM API calls strictly to verified edge cases.
Through our partnership with Packt, the IBridgePy community enjoys an exclusive 40% discount with promo code HUI40.
📅 Build Lab Snapshot
Friday, October 30, 2026
9:30 AM – 1:30 PM EDT (1:30 – 5:30 PM UTC)
4 Hours • Live & Interactive Hands-on Build Lab
Ben Auffarth, PhD (AI Consultant & Author)
Packt - ML & AI Engineering
40% Off with Code HUI40 ($89.99 vs $149.99)
Ready to Build Fast, Deterministic AI on CPUs?
Eliminate JSON parsing failures and build reliable, low-latency intelligence. Save 40% with code HUI40.
Enroll with 40% Discount (Code: HUI40) →Includes live build access, runnable notebooks, presentation slides, and Certificate of Completion.
Why Deterministic AI on CPUs is Vital for IBridgePy Algorithmic Traders
In live algorithmic trading, milliseconds count and system reliability is non-negotiable. If your trading system calls an LLM API to evaluate a trade setup or classify financial news sentiment, you cannot afford a 3-second latency stall or a malformed JSON error right as the market opens.
Here is how this deterministic CPU architecture transforms an IBridgePy automated trading setup:
- Zero GPU Overhead: Run high-performance encoder routing models locally on the very same commodity CPU or VPS running your IBridgePy bot, without spending thousands on GPU infrastructure.
- Zero Schema Parsing Failures: Avoid runtime Python crashes caused by LLM hallucinations. Encoders and conformal prediction produce deterministic vector scores and confidence intervals directly consumable by IBridgePy's trading loop.
- Intelligent Trade Triage & Signal Filtering: Classify news sentiment, macroeconomic headlines, and SEC alerts into deterministic signals with known uncertainty bounds before passing them to IBridgePy's order execution functions.
- Idempotent State Management: Use LangGraph's deterministic state machines to orchestrate complex execution workflows, ensuring your IBridgePy trading scripts never duplicate orders or lose track of trade state during network interruptions.
Core Techniques & Tools Covered:
- Long-Context CPU Inference: Deploy Liquid AI LFM2.5-Encoder and ModernBERT for sub-second text categorization and vector routing on standard CPUs.
- Few-Shot Fine-Tuning with SetFit: Rapidly train high-accuracy domain classifiers using contrastive learning with minimal labeled examples.
- Split Conformal Prediction: Calibrate distribution-free uncertainty intervals to guarantee statistical coverage before escalating queries.
- LangGraph State Machines: Design idempotent execution graphs that manage complex multi-step pipelines without unconstrained generative loops.
- Selective LLM Escalation: Route 95%+ of routine queries locally, invoking costly external LLM APIs only when uncertainty scores trigger a boundary condition.
- Post-Training Quantization: Maximize throughput on x86/amd64 processors using INT8/INT4 quantization.
Meet Your Instructor: Ben Auffarth, PhD
Ben Auffarth is an AI consultant, international author, and full-stack data scientist with over 15 years of experience spanning machine learning, generative AI, and high-throughput production data systems.
Holding a PhD in computational and cognitive neuroscience, Ben has engineered systems ranging from brain simulations on IBM supercomputers to real-time ML decision engines processing over 100,000 transactions daily. His work bridges rigorous statistical research with robust production software engineering.
What You Will Take Away:
- Complete Runnable Notebooks: Full code for the enterprise triage and execution engine developed during the lab.
- Full HD Session Recording: Review the step-by-step live coding and architectural patterns whenever needed.
- Speaker Presentation Slides: Complete reference diagrams and decision trees.
- Verified Certificate of Completion: Official credential from Packt recognizing your proficiency in low-latency AI engineering.
Frequently Asked Questions
Simply click any registration button on this page. Coupon code HUI40 is embedded in the link, discounting admission from $149.99 to $89.99 at checkout.
No. The entire point of this workshop is running efficient inference on standard commodity CPUs or free Google Colab instances.
Intermediate Python skills and basic familiarity with transformer concepts or LLM pipelines. All specific models and environments will be set up step-by-step.
Don’t Miss Out – Save 40% Today
Build bulletproof, low-latency AI systems that never break in production. Use code HUI40 to lock in your 40% discount before spots fill up.
Register on Luma with 40% Off →Discount applied automatically • 100% Online • Runnable Notebooks & Recording Included